How BAM Schedules Transactions

Updated Nov 20, 2026: BAM auction rounds are now a fixed 40 ms.
From the TPU to the leader, one 40 ms round at a time.
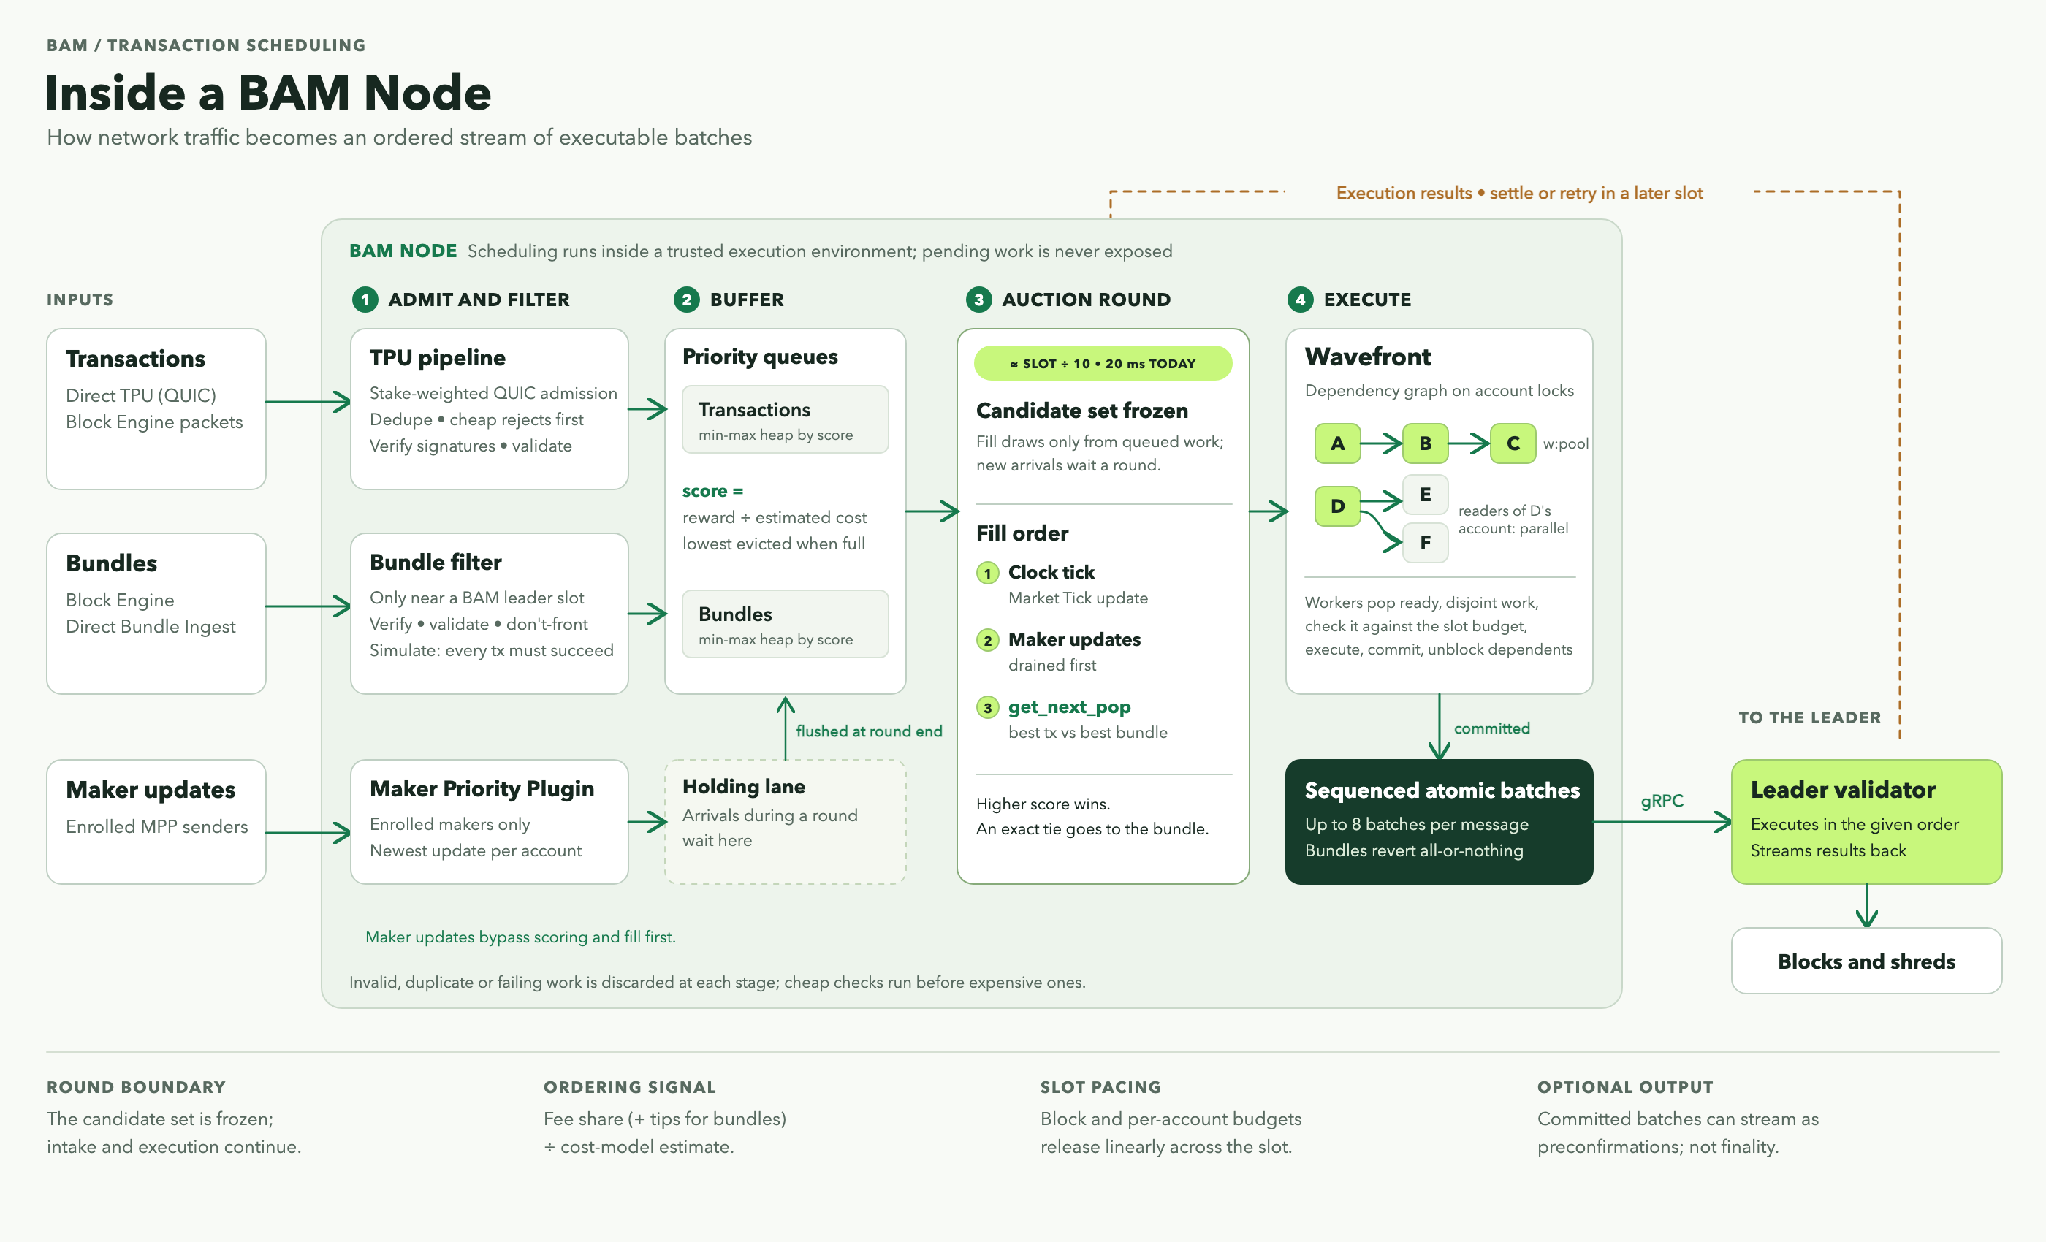
We get asked constantly: how exactly does BAM decide what goes into a block, and in what order? It’s not magic, but there is a lot of machinery under the hood. This post traces a transaction's exact path: how it hits a BAM Node, how we filter out the noise, how everything gets scored, how auction rounds freeze the state, and how our execution engine (Wavefront) rips through that ordering to build a block.
If you just want the actionable alpha on how to land your transactions more reliably, skip straight to the TL;DR at the bottom.
1. The TPU Pipeline
When a validator is hooked up to BAM, it gossips its BAM Node's TPU address. That means anything sent "direct to the leader"—whether from RPCs, wallets, or bots—hits the BAM Node first. If the validator disconnects or the BAM node goes unhealthy, it just reverts the gossip entry and takes its TPU back.
The BAM Node runs the same QUIC-based TPU as Agave, enforcing the exact same stake-weighted quality of service (SWQoS):
- Stake belongs to the sender, not the leader. When you connect, the node checks the stake of the identity on your QUIC cert. More stake equals more connections and concurrent streams.
- Unstaked senders still get a seat at the table, but their share is fixed and smaller. Under heavy load, unstaked traffic gets throttled to its floor first, then we hold staked peers to their proportional quotas.
- The forward port is strictly for the staked. It’s just there so staked validators can forward traffic they caught while not leading.
One recommendation if you actually care about your TPU landing rate, is to route through a staked connection using a service like Jito’s FullSend (or an RPC with solid SWQoS). Don’t just fire from an unstaked client and hope for the best.
Once a packet gets in the door, it hits a ruthless "cheap-first" pipeline before the scheduler even looks at it:
- Deduplication: A single thread merges TPU and Block Engine traffic, nuking exact duplicates using a bloom filter (which resets on a short timer).
- Cheap Rejects: Ed25519 signature verification is painfully expensive. If a packet's signature was already processed, or its blockhash or nonce is already dead, BAM drops it before sigverify to save the CPU.
- Sigverify: The survivors hit a pool of worker threads pinned to dedicated cores.
- Buffer & Score: Finally, the clean transactions are sanitized, lookup tables resolved, locks and compute limits validated, scored (more on this in Section 3), and tossed into a bounded priority queue.
Every step is connected by bounded channels. If a stage falls behind, it drops packets instead of blocking. A spam burst at step 1 won't choke out step 4.
2. Bundles: The First-Pass Filter
Bundles hit a BAM Node either from the Block Engine or straight over Direct Bundle Ingest (DBI). If you're routing through the Block Engine, you can target specific regions (e.g., hitting LON or DUB when targeting AMS or FRA leaders). Keep in mind, any bundle sent through Jito needs a minimum 1,000 lamport tip. To see who's running what, check the BAM validator API.
Block Engine region | BAM regions it forwards to |
Amsterdam | Amsterdam (ams) |
Dublin | Dublin (dub) |
Frankfurt | Frankfurt (fra), Šiauliai, Lithuania (sqq) |
London | London (lon) |
New York | New York/Newark (ewr), Ashburn (iad), Pittsburgh (pit) |
Salt Lake City | Salt Lake City (slc), Dallas (dfw), Los Angeles (lax), Seattle (sea) |
Singapore | Singapore (sin), Hong Kong (hkg) |
Tokyo | Tokyo (tyo) |
Before a bundle can compete, it has to pass sigverify and the bundle filter.
This filter is a restrictive first gate, by design. BAM sees a ton of hopeless traffic: bundles for slots where no BAM leader is up, stale bundles, guaranteed reverts. The goal is to trash the garbage as cheaply as possible so BAM spends real compute on the valuable ones. Checks run from cheapest to heaviest:
- Is a BAM leader actually up? If not, bundles get dropped immediately. BAM only buffers bundles right before a BAM leader slot.
- Shape check: Bundles must contain 1 to 5 transactions.
- Per-tx validation: BAM sanitizes, checks for known-bad blockhashes, resolves LUTs, validates locks, and ensures you aren't touching validator accounts (a strict no-go). It stops at the first failure.
- Front-running protection: The node strictly enforces the jitodontfront rule for direct arrivals (the Block Engine already handles this for routed bundles).
- Bank checks: BAM looks at transaction age, status, and whether the fee payer for the first txn actually has the funds.
- Simulation: The survivors get simulated against current state, top priority first. If any transaction in a bundle fails here, the whole bundle is dropped. The auction only looks at bundles that will execute cleanly.
If a bundle survives all this, it joins the bundle priority queue to be scored.
3. Sorting: The Universal Score
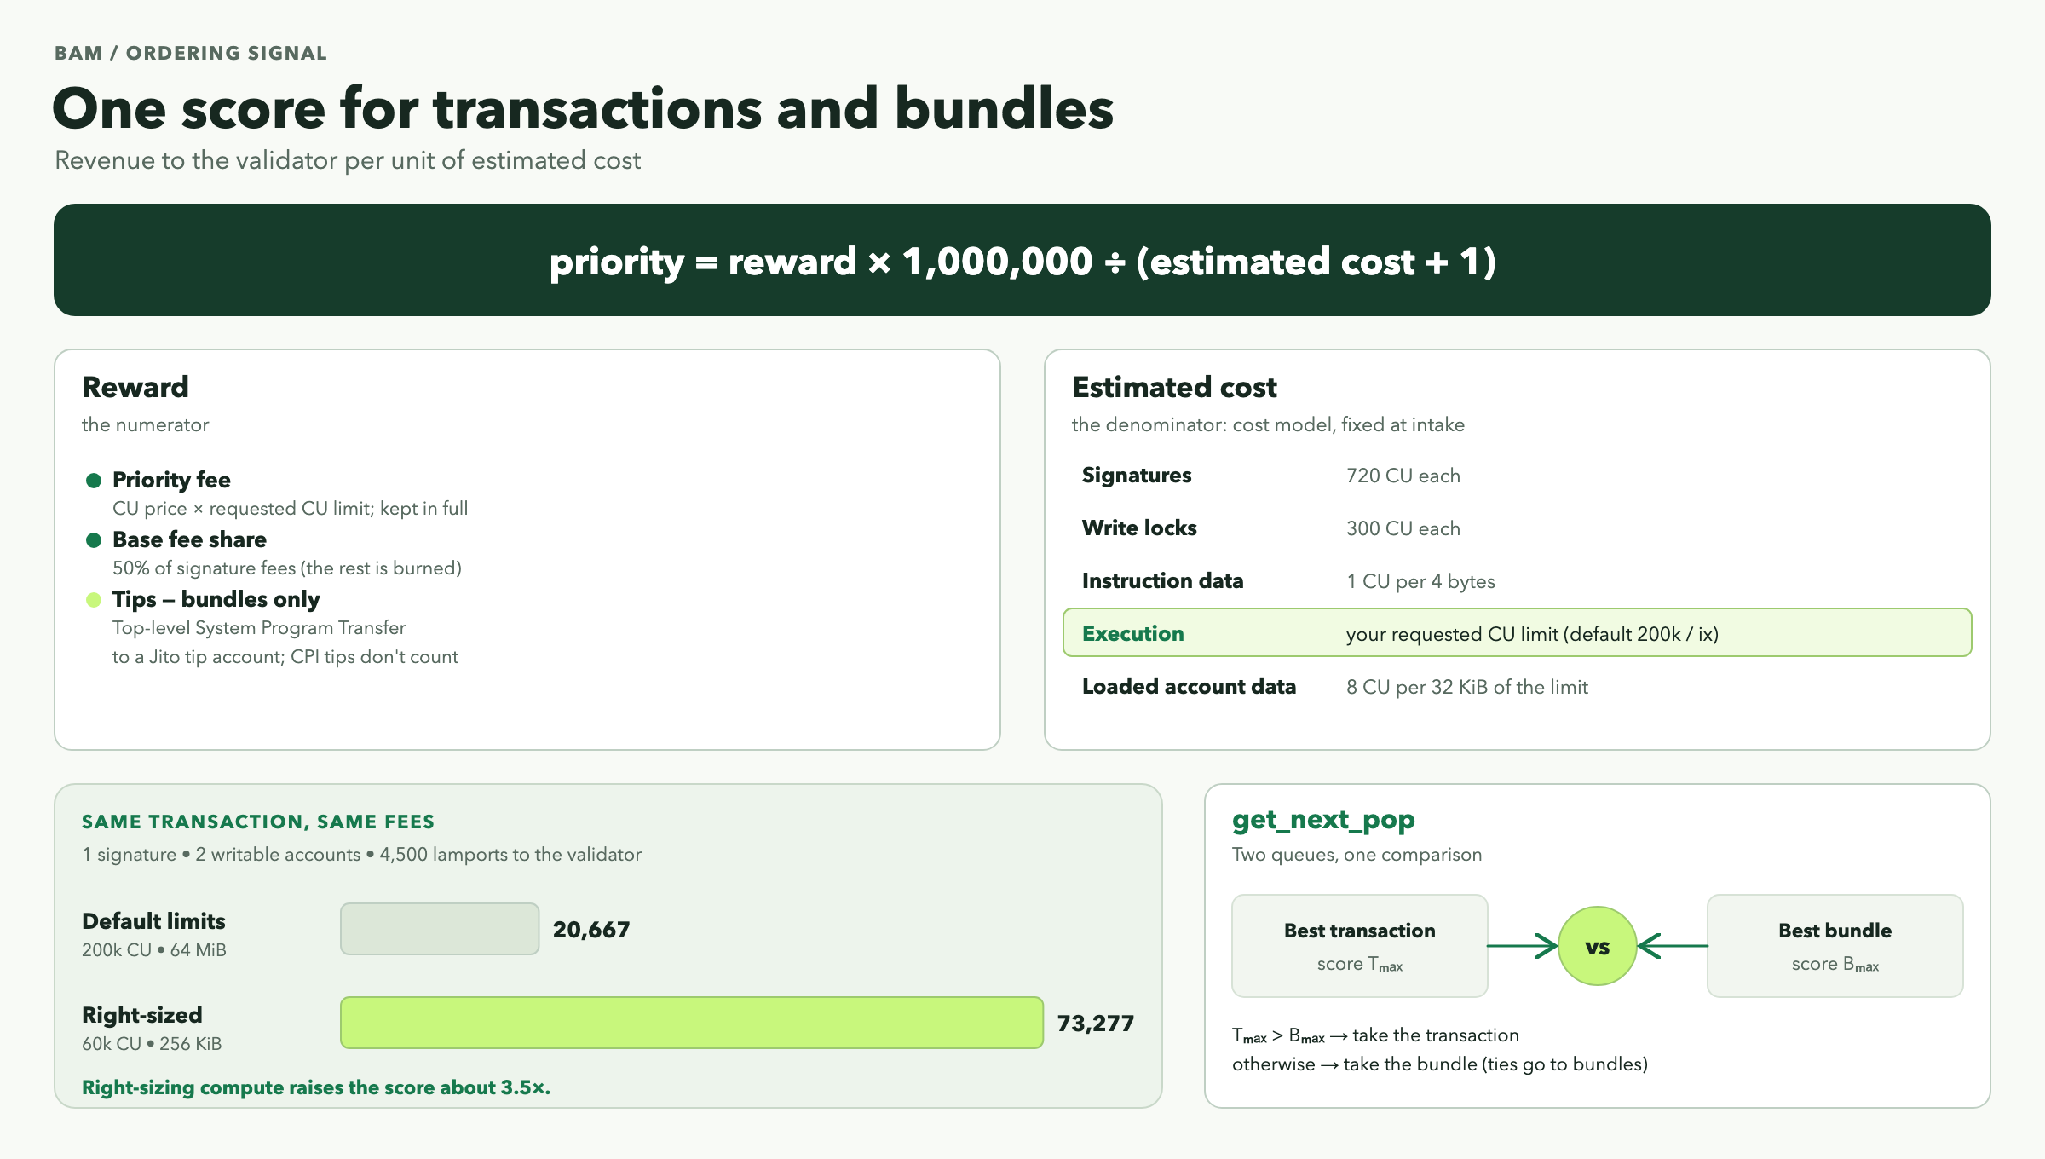
Transactions and bundles all compete on one critical metric: validator revenue per unit of estimated cost.
priority = reward × 1,000,000 / (cost + 1)
(The 1,000,000 multiplier just stops integer division from rounding small scores to zero, and the +1 prevents division by zero. Simple math).
The Numerator (Reward)
Single transaction | Bundle | |
Fee share | Priority fee (kept in full post-SIMD-0096) + 50% of the base signature fee | Same, summed across every transaction |
Tips | Not counted | Lamports sent to a Jito tip account by a top-level System Program `Transfer`, summed across the bundle |
An important note on tips: BAM ranks everything before execution. BAM can only count tips if it can read them directly from the transaction. If you try to tip via CPI or TransferWithSeed, the leader still gets the money if you land, but it won't help you win the auction. Standalone transactions compete solely on priority fees; bundles compete on fees plus explicit tips.
The Denominator (Estimated Cost)
Cost is a static estimate generated the moment the transaction arrives, not a simulation result. It has five parts:
Component | What drives it |
Signatures | 720 CU per signature (precompile signatures cost more) |
Write locks | 300 CU per writable account |
Instruction data | 1 CU per 4 bytes |
Execution | Whatever you set in SetComputeUnitLimit (defaults to 200k CU per instruction if absent) |
Loaded account data | 8 CU per 32 KiB of your loaded-accounts-data-size limit (64 MiB by default) |
Execution usually has the highest weight. The key rule is simple: every unit of compute you request but don't use actively tanks your score.
A Quick Example
Imagine a 1-sig transaction with 2 writable accounts and ~100 bytes of data. It pays a 5,000-lamport base fee (2,500 goes to the validator) and a 2,000-lamport priority fee. Total reward: 4,500 lamports.
Default limits (200k CU, 64 MiB) | Right-sized limits (60k CU, 256 KiB) | |
Estimated cost | 217,729 | 61,409 |
Priority score | 20,667 | 73,277 |
Same transaction, same money spent, but dialing in the limits boosts the score by 3.5x.
Now wrap two of those optimized transactions into a bundle and add a 50,000-lamport tip. The reward jumps to 59,000, cost is 122,818, and your score rockets to 480,381. That tip is what lets bundles get ahead of standard transactions.
How BAM Picks: get_next_pop
Transactions and bundles sit in separate min-max heaps. When the auction is filling a block, it just asks one question over and over:
- Does the top transaction score higher than the top bundle? If yes, take the txn.
- If no, take the bundle. Ties go to bundles.
- If one queue is empty, drain the other.
Arrival time doesn't matter. Within a queue, equal scores have no strict order. The only exceptions are the round's clock transaction (which advances the Market Tick program) and Maker Priority Plugin updates, both of which are drained first.
4. Auction Rounds & Frozen Inside One
BAM schedules in frequent batch auctions (FBA). It doesn't sequence transactions the millisecond they arrive, but instead groups them into short rounds and ranks the batch. If two transactions arrive 1ms apart in the same round, they're treated as simultaneous and sorted purely by score. So, for senders, it’s less important to try to be microseconds faster, they just need to be in the right round.
Round Lengths
BAM runs fixed 40 ms rounds, independent of slot length.
Until 2026-11-19, round length was derived from slot length (a tenth of the slot), so BAM’s rounds shrank with each of Solana’s SIMD-0525 slot-time reductions:
Slot time | 400 ms | 350 ms | 300 ms | 250 ms | 200 ms |
BAM round | 50 ms | 35 ms | 30 ms | 25 ms | 20 ms |
As of 2026-11-20, the round is a static 40 ms.
(Note: The Block Engine’s own auction runs on a fixed 50ms tick, completely independent of this).
Freezing the Competing Set
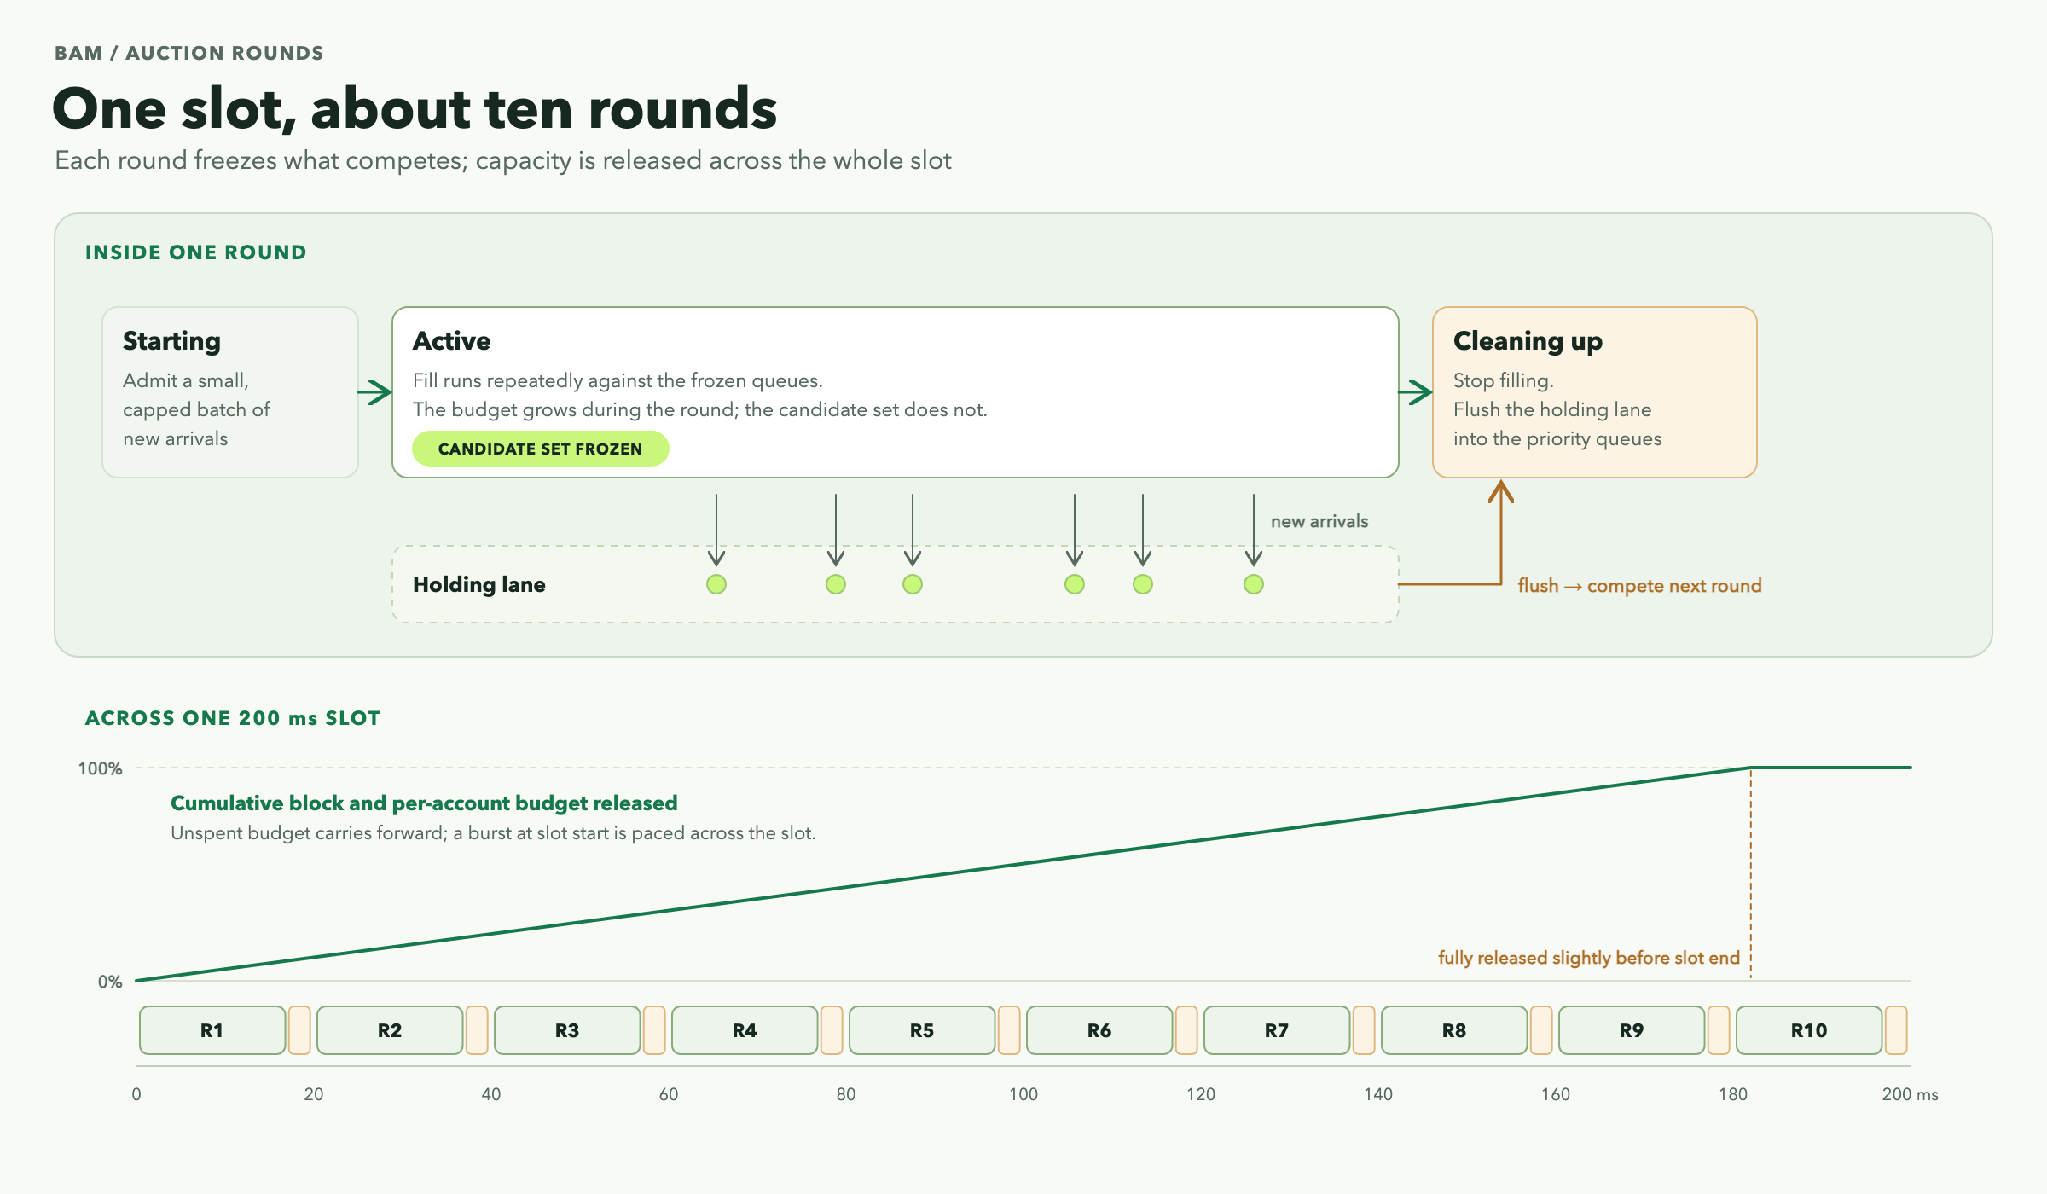
Each round is a fast state machine. The phase dictates how BAM handles fresh arrivals:
- At the start, it pulls a capped batch of new arrivals into the priority queues.
- While the round is active, new arrivals are sidelined in a holding lane. The fill loop only pulls from the priority queues. The competing set is frozen.
- When the round ends, the holding lane flushes into the priority queues to compete in the next round alongside the losers from the previous one.
Pacing the Slot
Winning a round only matters if there’s block capacity left. BAM releases the block compute limit and the per-account write limit linearly across the slot, cutting off slightly early so it has time to actually reach the leader.
The per-account limit is the real bottleneck for most searchers. If everyone is hammering the same oracle or liquidity pool, they’re all fighting for the same per-slot budget, and fees dictate who wins. If large bundles start dragging the committed block cost behind the linear schedule, the scheduler temporarily pauses bundles and fills with plain transactions until we catch back up.
5. Wavefront: From Ordered to Executed
Ranking transactions and bundles is only one part of the equation. The scheduler has to execute the work speculatively to ensure it actually fits before committing to the leader. It has to do this in order, respect account conflicts, and move fast enough to keep a 20ms round fed and move fast enough to keep a 40 ms round fed.
Here’s where Wavefront comes in. Since August 2026, this dataflow scheduler has been BAM’s sole execution engine.
Why We Built It
BAM’s old engine kept a priority graph of account locks on the auction thread. It would drain ready work to simulation workers, wait for results, commit them, and unblock the next items. The graph was fast, but the round trips increased latency. On mainnet, a 40-deep chain of trades on a single hot pool spent milliseconds just waiting in transit between the auction thread and the workers.
How Wavefront Fixes It
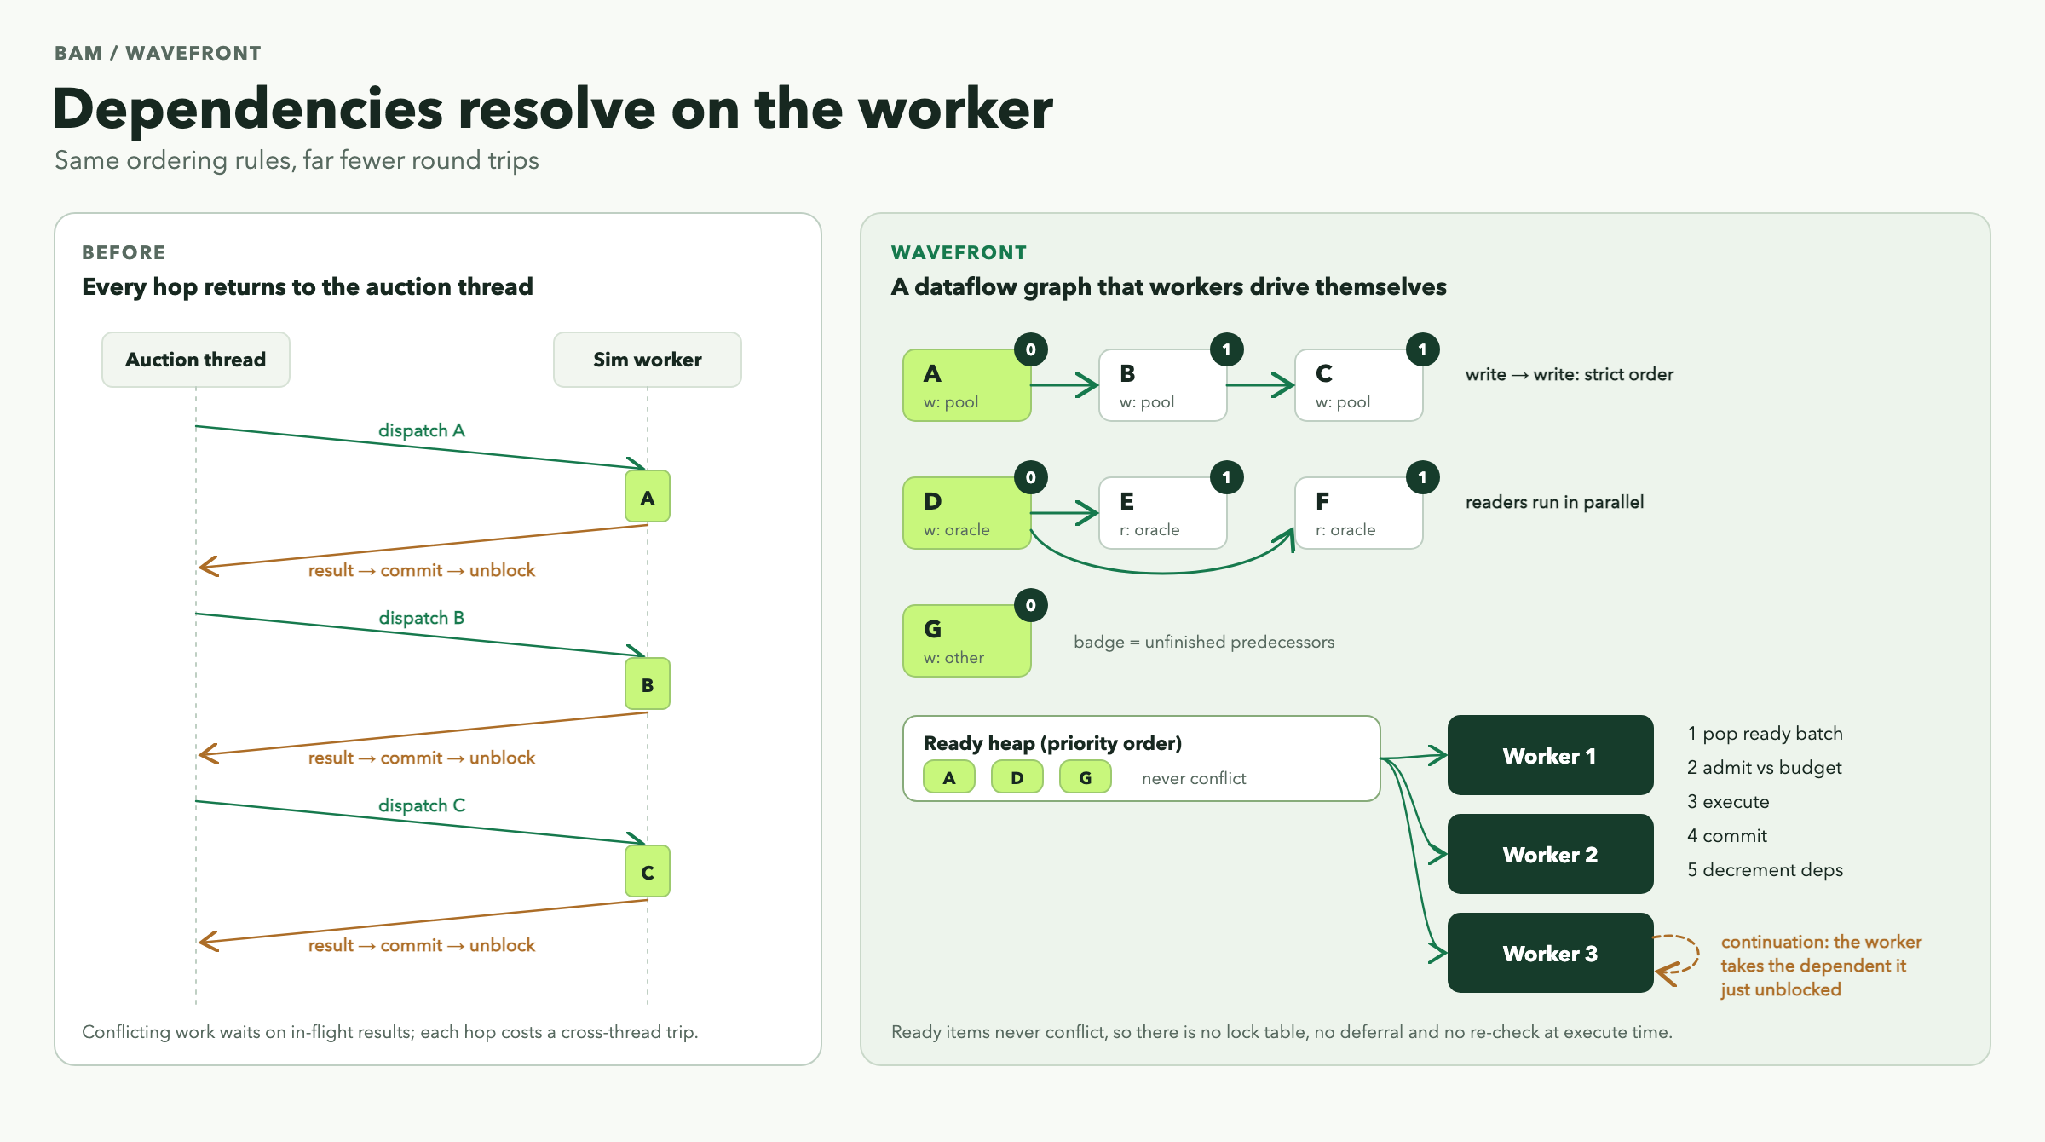
Think of Wavefront like a CPU's Tomasulo algorithm applied to Solana:
- The Graph: Built in priority order. Each item gets a node, with edges pointing to earlier conflicting items (write-after-write, write-after-read, read-after-write).
- The Ready Heap: Each node tracks its unfinished predecessors. When that hits zero, it drops into a priority-ordered ready heap.
- Worker Autonomy: This is where the magic happens. A worker grabs a batch of ready items, checks the budget, executes them against a speculative bank, and commits them. Then the worker decrements the predecessor counts of dependent items itself. Unblocking the next trade is a single atomic operation—no round trips required.
- Continuations: If finishing an item unblocks a higher-priority dependent, the worker just grabs it immediately, bypassing the heap entirely. A long ladder of trades on a single pool now rips back-to-back on a single core.
The result? Zero lock tables, zero deferred work, and parallel execution for unrelated accounts. Wavefront has been one of BAM’s most important scheduler upgrades, and responsible for its increase in performance across all relevant block packing metrics
6. Making It Fast
A few of the heavy-lifting optimizations powering the current scheduler:
- Cheap work first: Known-bad txs die before sigverify. DBI credentials get checked before request bodies are read. Bundles are filtered before simulation.
- Zero-copy: Transactions are parsed in place as views and passed by handle. Hot-path allocations dropped by over 50%.
- Worker-owned cascades: One dependency hop in Wavefront is just an atomic decrement and a heap push. In microbenchmarks, that hop costs ~60 nanoseconds.
- Disjoint batching: Up to eight non-conflicting items share an execution call to amortize SVM fixed costs. (Bundles always run solo).
- Spin, then park: Idle workers spin with exponential backoff before sleeping, cutting wake-up latency in half.
- Cache-conscious: Graph nodes live inline in an arena, aligned to cache lines. Shrinking work items from 2.8 KB to 630 bytes made graph filling ~40% faster.
- Lock-free reads: The speculative bank reads block-cost totals from atomics, dropping snapshot times from 700ns to 70ns.
- Background reaping: Dropping a slot's speculative state happens on a background thread now, saving tens of milliseconds.
Today, Wavefront workers spend 80–90% of their time actually executing transactions inside the SVM. The scheduling overhead is essentially gone.
What This Means For BAM Senders (The TL;DR)
- Right-size your compute. Set SetComputeUnitLimit accurately, and dial back your loaded-account-data limit. Over-requesting directly penalizes your priority score.
- Tip properly. Use a top-level System Program transfer. CPI tips do not count toward BAM’s auction ranking. (And remember the 1,000 lamport minimum).
- Target your geography. If you're allowlisted for DBI, use it. Otherwise, route bundles through the optimal Block Engine region (e.g., LON/DUB for AMS/FRA leaders).
- Pay both a tip and a priority fee on bundles. Standard leaders rank on tips alone; BAM leaders count both.
- Play the round, not the microsecond. Being 200 µs faster inside a 40ms round does nothing. Missing the round costs everything.
- Stop spamming duplicates. We deduplicate across multiple layers. Spamming doesn't help you land.
- Beware the per-account limit. On hot accounts, the budget is capped. Optimize your compute footprint so more of your transactions fit, because throwing more money at it won't increase the cap.
- Stake your TPU connection. If you rely on the TPU path, send over staked connections. Unstaked traffic gets throttled the second load spikes.